Onde Inference
Private AI inference for the enterprise
- Upvotes
- 0
- DR
- 8 no change since last check
- Followers
- 0
Native on-device LLM inference SDK that runs language models locally on Apple Silicon at 85ms latency with zero server cost and complete data privacy.
About Onde Inference
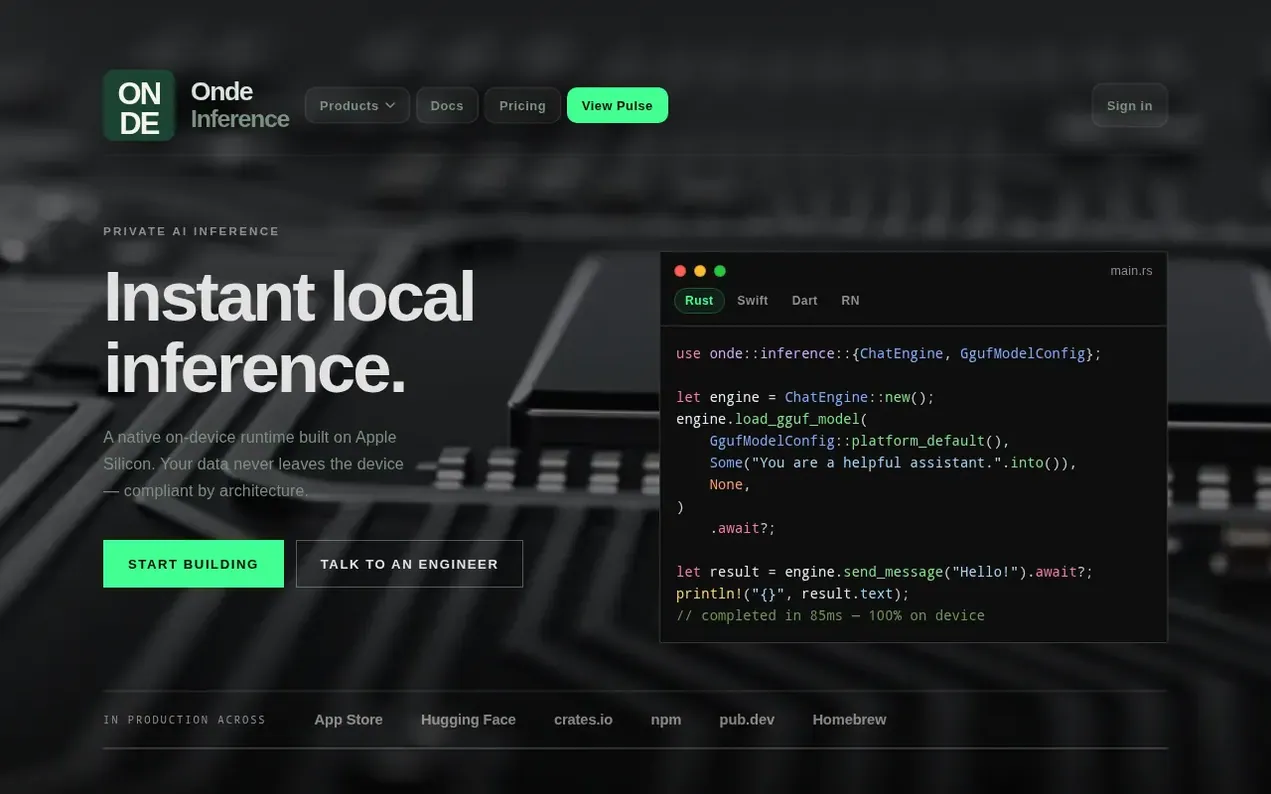
Onde Inference is a native on-device runtime that runs language models directly on Apple Silicon devices without sending data to the cloud. It achieves 85ms first-token latency with zero server costs for inference that stays entirely on-device. The SDK ships first-class support for Swift, Rust, Flutter, and React Native, sharing the same underlying GGUF runtime.
When a device hits its memory or compute limit, apps can seamlessly burst to Onde Cloud with a single line of code change, providing an OpenAI-compatible inference API. The platform is built for teams in healthcare, finance, and regulated industries where data compliance is critical. HIPAA and GDPR compliance are built into the architecture since prompts, tokens, and results never leave the user's device.
Onde Inference is built and operated by Splitfire AB, a Swedish software company that also publishes native apps on Apple platforms. The team owns the entire execution layer from device runtime to cloud infrastructure, writing in Rust and Swift for performance-critical inference paths.
- llm sdk
- apple-silicon
- zero data egress
- edge compute
- hipaa compliant
- private inference
- on-device ai
Features worth knowing
- Native SDKs for Swift, Rust, Flutter, React Native with single unified API
- 85ms first-token latency on Apple Silicon
- Zero server cost for on-device inference
- No data egress - inference stays on-device
- GDPR and HIPAA compliant by architecture
- OpenAI-compatible Onde Cloud API
- Global state sync between device and cloud
- AES-256 encrypted cloud burst
- Data never trained on - no model fine-tuning on customer data
Pricing
Pricing model: Freemium
SDK: Free for building. Device plans: Garage $0/mo (up to 5 active devices), Pro $49/mo + $0.05 per active device, Scale custom pricing. Onde Cloud: Per million tokens ranging from $0.12 to $6.00 for input tokens, $0.005 to $1.20 for cached input, and $0.33 to $30.00 for output tokens depending on t
Onde Inference metrics
| Metric | Value |
|---|---|
| Domain Rating | 8 no change since last check |
| Trust Flow | 2 no change since last check |
| Citation Flow | 26 no change since last check |
| Referring domains | 29 no change since last check |
| External backlinks | 351 no change since last check |
Ahrefs Domain Rating scanned 1 Nov 2026, updated 1 Nov 2026. Main topic: Science/Environment (2). Majestic scanned 1 Nov 2026, updated 1 Nov 2026. Link stats via Majestic. Trust Flow, Citation Flow and Topical Trust Flow are trademarks of Majestic-12 Ltd.
Onde Inference domain facts
Reveal the domain facts
| Domain age | 7 months |
|---|---|
| Registered | |
| Expires | |
| Registrar | NameCheap, Inc. |
| DNSSEC | Not signed |
Compare and explore
FAQ
- How fast is on-device AI inference on Apple Silicon?
- Onde Inference runs at 85ms first-token latency on Apple Silicon devices, compared to 800ms or more for a typical cloud API round-trip. Inference runs entirely on-device with no network request in the critical path.
- Does data leave the device when using Onde Inference?
- No. When using the on-device SDK, all inference runs in-process on the device. No prompt, token, or result is sent over the network. The only network activity is the initial one-time model download from HuggingFace Hub.
- Which programming languages does Onde Inference support?
- Onde Inference ships first-class SDKs for Swift (iOS, macOS, tvOS, visionOS, watchOS), Rust (macOS, Linux, Windows), Flutter/Dart (iOS, Android, macOS), and React Native (iOS, Android). All four share the same underlying GGUF runtime and OndeChatEngine API surface.
- What is Onde Cloud?
- Onde Cloud is an OpenAI-compatible inference API. It runs the same GGUF models as the on-device SDK. When a device hits its memory or compute limit, apps can route requests to Onde Cloud with a single line of code change. Auth uses a Bearer token scoped per app.
- When should I use the cloud instead of on-device inference?
- Use Onde Cloud when the task is larger than the device: long contexts, heavy reasoning, or a device that is too old to run the model. Your app keeps running on-device by default and calls Onde Cloud with the same app key when it needs to.
Leave a review for Onde Inference
Nobody has reviewed Onde Inference yet. Start things off.
A review is always free and can never be paid for. Go to the reviews and discussion
Reviews and chat · Product news · Send it on · Run this company? Claim it here · Report it
Onde Inference has a free listing. The owner can unlock the full profile with a paid launch for $5:
- Founder story (locked)
- Milestones (locked)
- Demo video (locked)
- Dofollow website link (locked)
Alternatives to Onde Inference
Computable
Open-source price index for GPU compute updated every 15 minutes
AI inference & GPU cloud0 votes. Log in to add your vote for ComputableMaritime
Cloud computers for AI agents, billed per second
AI inference & GPU cloud0 votes. Log in to add your vote for MaritimeIQ Routing
See and control your team's AI use
AI inference & GPU cloud0 votes. Log in to add your vote for IQ RoutingQuip Network
The worldwide quantum computer marketplace for accessing quantum processors on demand and earning by contributing compute
AI inference & GPU cloud0 votes. Log in to add your vote for Quip Network