LLMBenchmark.ai
LLM leaderboard tracking 382 AI models with benchmark scores, API prices and cost per solved task, updated daily
- Upvotes
- 0
- DR
- 2 no change since last check
- Followers
- 0
- Since
- 2019
About LLMBenchmark.ai
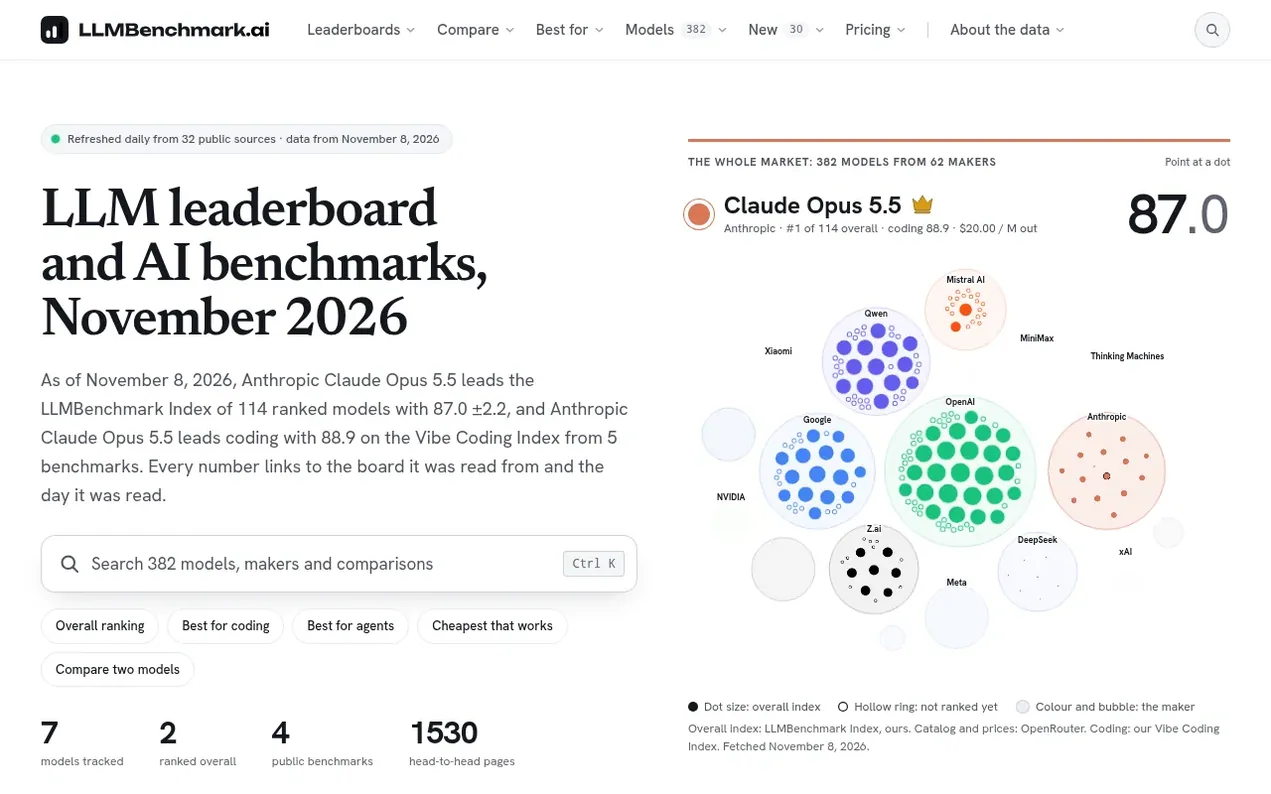
LLMBenchmark.ai provides a unified leaderboard for 382 AI language models, measuring performance across multiple dimensions including overall capability, coding, agentic work, reasoning, math, knowledge, and web design. Each model's scores come from independent public benchmarks, with prices from OpenRouter and other API providers fetched daily.
The site computes two proprietary metrics: the Vibe Coding Index, a weighted average of six public coding benchmarks, and cost per solved task, which divides API pricing by the success rate on SWE-bench Verified tasks. All data is licensed CC BY 4.0 for reuse, and available as JSON through a free API and MCP server.
Built by Take Group, a Polish software company that runs on AI agents, LLMBenchmark.ai was launched in October 2026 to put current scores and prices side by side with their sources, so developers can choose models for real work.
- coding-index
- llm
- model-comparison
- api pricing
- benchmarks
- leaderboard
Features worth knowing
- Vibe Coding Index measuring performance on coding tasks
- Cost per solved task metric for real-world efficiency
- Daily data refresh from 32 public benchmark sources
- Compare any two models side by side
- API and MCP server for programmatic data access
Pricing
Pricing model: Free
Free; data available as JSON, via free API and MCP server
Follow LLMBenchmark.ai and hear about their milestones, new launches and demo videos by email. Stop any time.
LLMBenchmark.ai metrics
| Metric | Value |
|---|---|
| Domain Rating | 2 no change since last check |
| Trust Flow | 5 no change since last check |
| Citation Flow | 26 no change since last check |
| Referring domains | 17 no change since last check |
| External backlinks | 451 no change since last check |
Ahrefs Domain Rating scanned 10 Nov 2026, updated 8 Nov 2026. Main topic: Home/Consumer Information (5). Majestic scanned 8 Nov 2026, updated 8 Nov 2026. Link stats via Majestic. Trust Flow, Citation Flow and Topical Trust Flow are trademarks of Majestic-12 Ltd.
LLMBenchmark.ai domain facts
Reveal the domain facts
| Domain age | 23 days |
|---|---|
| Registered | |
| Expires | |
| Registrar | NameCheap, Inc. |
| DNSSEC | Not signed |
LLMBenchmark.ai launch results
| Measure | At launch, then latest |
|---|---|
| Domain Rating (Ahrefs) | 2 to 2 no change since launch 8 Nov 2026, then 10 Nov 2026 |
| Trust Flow (Majestic) | 5 first measured 8 Nov 2026 |
| Referring domains (Majestic) | 17 first measured 8 Nov 2026 |
Day 2 since launch. Next receipt: day 30, 8 Dec 2026. The figures report a change; they do not say what caused it, and many things can. No figure here is a guess.
Launching something soon?
Free tips from Best Digital Launch for getting ready, launch day, the week after and what to do next.
- Set up
- On launch day
- The days after
- Beyond launch
Compare and explore
FAQ
- What is the best LLM right now?
- As of November 8, 2026, Anthropic Claude Opus 5.5 leads the LLMBenchmark Index with 87.0 ±2.2 across 114 ranked models. The best model depends on the job, with separate rankings for coding, agentic work, reasoning, math, knowledge and web design.
- Which LLM is best for coding?
- Anthropic Claude Opus 5.5 leads the Vibe Coding Index with 88.9, based on five coding benchmarks. 102 models have a coding score.
- What is the best cheap LLM?
- Among models at or under $1 per million output tokens on OpenRouter, DeepSeek V4.1 Flash has the highest overall index at 70.1 for $0.84. For coding, cost per solved task is a better measure of value.
- Why do some cells say No data?
- Because that benchmark has not measured that model. The site leaves gaps visible rather than estimating numbers, so every figure shown was published by someone you can check.
- Which LLM is best for agents and tool use?
- Anthropic Claude Fable 5.1 leads our Agentic Index with 82.2 as of November 8, 2026. The index averages live benchmarks of tasks where a model works over many steps, in a terminal or a browser, and calls tools.
Leave a review for LLMBenchmark.ai
Nobody has reviewed LLMBenchmark.ai yet. Start things off.
A review is always free and can never be paid for. Go to the reviews and discussion
Reviews and chat · Product news · Send it on · Run this company? Claim it here · Report it
LLMBenchmark.ai has a free listing. The owner can unlock the full profile with a paid launch for $5:
- Founder story (locked)
- Milestones (locked)
- Demo video (locked)
- Dofollow website link (locked)
Makers
- Bartłomiej KrawczykFounder
Alternatives to LLMBenchmark.ai
FastAIToken
FastAIToken provides unified authentication, intelligent routing, automatic failover and usage management across 40+ leading AI models through a single API.
LLM APIs & models0 votes. Log in to add your vote for FastAITokenSingIt
One API key for 200+ AI models below list price, with pay-per-answer x402 payments or prepaid balance
LLM APIs & models0 votes. Log in to add your vote for SingItWiro AI
One unified API for accessing 1000+ AI models across image, video, audio, and language generation
LLM APIs & models0 votes. Log in to add your vote for Wiro AINeedle 3
Foundation model for mobile, wearables, robots, smart home, automotive and microcontrollers
LLM APIs & models0 votes. Log in to add your vote for Needle 3